
by Striped Giraffe Team
5. October 2026
Reading time: 10 Minutes
Building an AI-Ready Data Environment
Enterprise AI scales successfully only when the underlying data environment can deliver trusted context, stable semantics, governed knowledge, and operational consistency continuously over time — across every model, workflow, and decision layer.
An AI-enabled data environment is a data architecture and operational framework that continuously supplies AI systems with high-quality, traceable, and access-controlled data. It combines data quality, data governance, semantics, AI serving, and observability into a robust foundation for the productive use of AI.
Part 1 showed why enterprise data often fails once AI moves from pilot to production: fragmented definitions, hidden quality issues, unmanaged content, access friction, and unclear ownership.
This second article turns those failure modes into a practical target model. It outlines five capabilities enterprises need to supply AI systems with reliable context, governed knowledge, and production-grade data flows at scale.
The model consists of five connected modules. They do not represent a rigid implementation sequence. After the initial consumption assessment, organizations usually develop serving capabilities, semantics, governance, and observability in parallel, prioritizing the controls required by the most valuable AI use cases.
- Module 1: Define AI consumption patterns before designing the architecture
- Module 2: Build dedicated AI-serving layers
- Module 3: Operationalize shared semantics and ownership
- Module 4: Govern unstructured knowledge as a production asset
- Module 5: Operate with continuous data quality and AI observability
Module 1:
Define AI consumption patterns before designing the architecture
Enterprise data environments rarely support a single AI workload.
Retrieval-based copilots, forecasting models, recommendation systems, operational assistants, and agentic workflows consume data in different ways. A solution designed for low-latency recommendations therefore has different requirements from a knowledge assistant that must retrieve authoritative documents with source-level permissions.
Before selecting platforms or designing pipelines, organizations should map each planned workload against six questions:
- Which sources and data products are authoritative?
- Which entities, definitions, and historical relationships must remain consistent?
- What quality, freshness, latency, and availability levels does the workload require?
- Which data is sensitive, and which source-system permissions must be preserved?
- What lineage, evidence, and audit trail must be available for outputs or actions?
- Which regulatory, retention, and business-policy constraints apply?
The assessment should involve:
- data architecture teams
- AI engineering
- governance leaders
- security teams
- and business domain owners
Its primary deliverable is an AI consumption inventory that connects every prioritized workload to its sources, consumption mode, semantic dependencies, service levels, controls, and accountable owners.
This inventory does not create a separate architectures for every AI system. It identifies which capabilities can be shared and where domain-specific patterns remain necessary.
Module 2:
Build dedicated AI-serving layers
Many enterprise data platforms were originally designed for reporting, dashboarding, and historical analytics. AI systems introduce additional operational requirements that frequently justify a dedicated AI-serving layer positioned between operational systems and AI applications.
This layer typically becomes responsible for:
- semantic modeling
- semantic enrichment
- retrieval optimization
- feature consistency
- contextual assembly
- metadata standardization
- vector indexing
- and governed AI access patterns
Meeting these requirements does not always require a physically separate platform. An AI-serving layer can be a logical set of capabilities built into an existing lakehouse, data mesh, integration platform, or knowledge architecture. The key is to separate reusable serving logic from individual AI applications so that every team does not rebuild the same pipelines, permissions, and transformations.
Governed data products form the foundation of this layer. Each product should have an accountable owner, a defined purpose, documented semantics, a stable consumption interface, quality and freshness objectives, lineage, and enforceable access rules. These contracts make data easier to discover and consume while reducing manual extracts, approval chains, local copies, and shadow pipelines.
Curated retrieval collections
Enterprise copilots and retrieval-augmented generation (RAG) systems should retrieve from curated collections rather than indiscriminately exposing complete repositories. A collection should identify authoritative content, retain document and artifact lineage, carry access classifications, and define review and freshness policies. Chunking and enrichment should reflect the domain: contracts, engineering specifications, service procedures, and product information rarely require the same segmentation logic.
Metadata enrichment pipelines
Metadata is a production dependency for enterprise AI systems.
Organizations therefore build enrichment pipelines capable of attaching:
- ownership
- business taxonomy
- sensitivity labels
- lineage references
- retention rules
- source authority indicators
- and semantic tags
to structured and unstructured assets.
Automated classification accelerates this work, but high-impact attributes still require validation and clear accountability.
Feature-serving environments
Predictive AI systems often depend on feature-serving layers designed to maintain consistency between:
- model training
- validation
- experimentation
- and production inference
This is where feature stores become operationally important.
Companies such as Uber, Airbnb, and others operating large-scale ML platforms publicly documented how centralized feature management improved consistency between training and production environments.
These architectures reduce:
- feature drift
- duplicated transformation logic
- inconsistent training datasets
- and operational instability
Module 3:
AI systems consume semantics continuously.
As enterprise AI adoption expands, inconsistencies in business terminology increasingly propagate directly into:
- retrieval pipelines
- recommendations
- forecasting logic
- agentic workflows
- and generated responses
Without stable semantic controls:
- retrieval systems assemble conflicting context
- forecasting pipelines consume inconsistent historical records
- recommendation systems inherit fragmented behavioral signals
- and autonomous workflows may act on incomplete operational understanding
Organizations therefore invest heavily in semantic stabilization mechanisms, like:
- canonical business definitions
- governed KPI logic
- enterprise business glossaries
- entity resolution frameworks
- semantic lineage
- and cross-domain governance processes
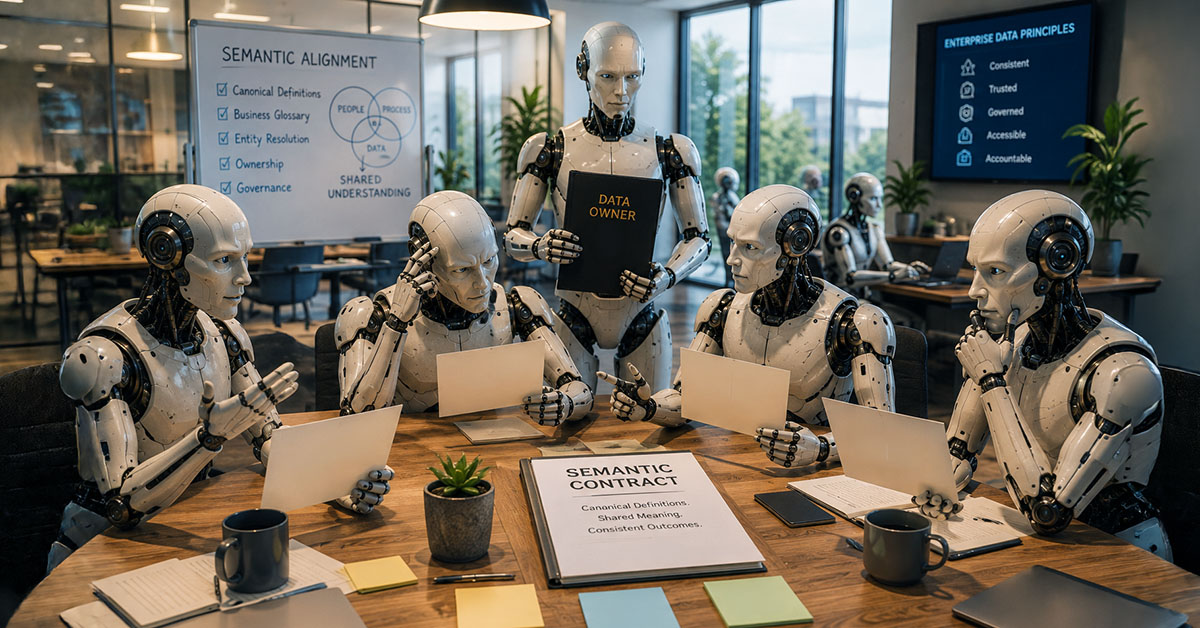
These controls should be expressed through reusable semantic contracts and interfaces rather than remaining confined to documentation.
Ownership is equally important.
A governance council can resolve cross-domain conflicts, but it cannot replace operational accountability. Every critical data product, retrieval collection, and semantic definition needs a named owner responsible for quality, freshness, access, lifecycle decisions, and remediation. Platform teams provide shared services; domain owners remain accountable for meaning and fitness for use.
Module 4:
Govern unstructured knowledge as a production asset
As Part 1 explained, unstructured repositories often contain the enterprise context AI needs most, but they also contain duplicated, outdated, low-authority, and insufficiently classified material. The answer is not simply to embed more documents. It is to establish an authoritative knowledge model.
This model should define:
- which sources and versions are authoritative for each domain
- who reviews, approves, archives, and retires content
- how authority, freshness, sensitivity, and retention are represented in metadata
- how redundant, obsolete, and trivial (ROT) content is identified and removed
- and how retrieval behavior is validated before collections are exposed to AI systems
Permissions must remain intact as documents are parsed into text, tables, images, chunks, embeddings, and indexes. Source-system entitlements, privacy classifications, and least-privilege rules should therefore propagate through the complete ingestion and retrieval flow. Derived artifacts must remain traceable to the original source so that outputs can be investigated, corrected, and reprocessed reliably.
Module 5:
Operate with continuous data quality and AI observability
AI data quality is use-case-specific. Data does not need to be perfect in every dimension, but it must be fit for the decision, response, or action it supports. Quality objectives should therefore cover the dimensions relevant to each workload, such as completeness, accuracy, timeliness, representativeness, semantic consistency, historical correctness, and label quality.
These objectives should be translated into operational service levels. Depending on the workload, these may define maximum synchronization latency, ingestion frequency, permissible data age, availability targets, and expiration rules for time-sensitive context.
Observability then connects these source-level controls to the behavior of the AI system. The monitoring model should distinguish among:
- RAG and copilots: retrieval precision and recall, ranking quality, groundedness, citation correctness, source authority, freshness, access enforcement, latency, and cost
- predictive AI: validation failures, feature availability, training-serving skew, feature and distribution drift, concept drift, historical signal integrity, and model performance
- agentic workflows: tool-selection accuracy, policy enforcement, action outcomes, exceptions, and complete audit trails
- cross-cutting data and knowledge controls: semantic drift, lineage breaks, freshness SLA violations, changes in source authority, and unexpected changes in retrieval or output behavior
Retrieval systems should also undergo regression testing whenever repositories, metadata, chunking strategies, embedding models, or indexes change. This helps determine whether relevant information remains consistently discoverable as the knowledge environment evolves.
Rather than treating every inaccurate answer as a model hallucination, teams should trace ungrounded or inconsistent outputs back through the retrieved context, source lineage, semantic definitions, permissions, and pipeline state. Recurring failure patterns and output stability should be evaluated against controlled test sets – without expecting nondeterministic models to produce identical responses.
The objective is not only detection but remediation: correct the source or metadata, rebuild the relevant artifact or feature, re-index or retrain where necessary, and validate the result against the same tests.
This feedback loop requires service levels, incident ownership, escalation paths, and recurring review. Observability becomes an operating discipline, not a dashboard added after deployment.
Security, privacy, and compliance span all five building blocks
Security and compliance should not be treated as a final approval stage. Data classification, identity propagation, policy enforcement, retention, auditability, and regulatory obligations must be designed into the consumption inventory, data products, retrieval collections, semantic controls, and monitoring model from the outset. This is particularly important when AI systems can initiate business actions rather than merely generate recommendations.
Conclusion
Preparing enterprise data for AI requires more than consolidating repositories or deploying a new platform. It requires an operating environment in which data and knowledge are supplied through governed products, explicit semantics, controlled access, reliable serving patterns, and measurable service levels.
The practical starting point is an AI consumption inventory for a small number of high-value workloads. From there, organizations can identify which shared capabilities already exist, where ownership and quality controls are missing, and which investments will reduce risk or accelerate multiple use cases at once.
Organizations that build these capabilities as reusable enterprise infrastructure are better positioned to move AI from isolated pilots into reliable, governed production systems.
In enterprise AI, sustainable competitive advantage increasingly depends on whether organizations can operationalize trusted data environments capable of continuously supplying reliable context, governed knowledge, and stable semantics at production scale.
You might also like:
- AI Data Readiness, Part 1: Why Most Enterprise Data Still Fails AI » Learn more
- AI in E-Commerce (E-Book) » Learn more
- What Google’s Universal Commerce Protocol Signals for the Future of B2B Commerce » Learn more
- Agentic Commerce: Where Conversations Become Transactions » Learn more
- Agentic Commerce: Winners, Losers, and the Forces Behind the Change » Learn more
- Agentic Commerce: Strategic Priorities for Executive Leaders » Learn more
- Generative AI unlocks the value of unstructured data in insurance » Learn more