
by Striped Giraffe Team
28. September 2026
Reading time: 9 Minutes
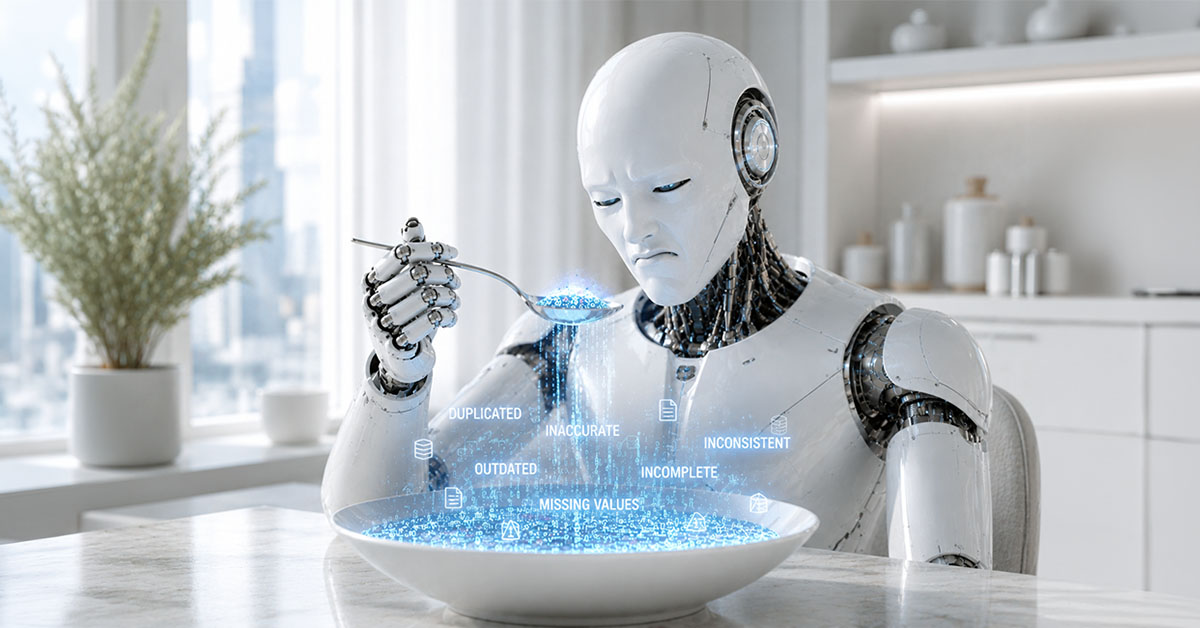
Why Most Enterprise Data Still Fails AI
AI initiatives rarely fail in the demo phase. Most failures emerge later — when models are exposed to the realities of enterprise data environments that were never designed to support AI systems operating at scale.
On paper, many organizations appear well prepared. They have modern data platforms, cloud infrastructure, integration layers, dashboards, governance programs, and years of accumulated data. Internal assessments often classify these environments as “AI-ready.”
Yet once AI systems begin consuming enterprise data directly, the same issues surface repeatedly:
- inconsistent outputs
- unreliable retrieval
- contradictory signals
- low trust in generated responses
- escalating manual validation
- and growing operational overhead around supposedly automated systems.
These problems rarely originate in the model itself. They emerge from the condition, structure, accessibility, and operational behavior of the underlying data.
Traditional analytics environments could tolerate many of these limitations because human users continuously compensated for them. Analysts reconciled discrepancies manually. Business teams interpreted ambiguous fields based on institutional knowledge. Reporting pipelines absorbed inconsistencies through local fixes and downstream adjustments.
AI systems operate differently.
Large language models, recommendation engines, forecasting systems, copilots, retrieval pipelines, and autonomous workflows consume data directly, continuously, and at scale. Under these conditions, inconsistencies that previously remained manageable become embedded into prompts, features, retrieval contexts, and generated outputs.
As a result, organizations increasingly discover that having large volumes of enterprise data does not automatically translate into usable AI-ready data.
Data remains fragmented across systems
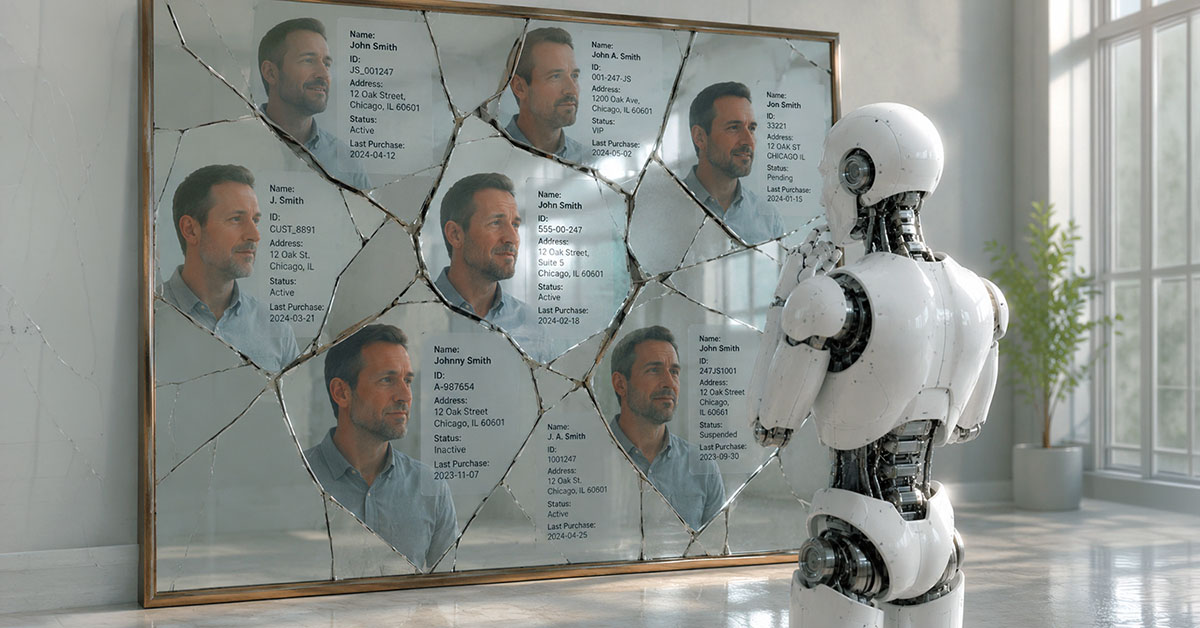
Most enterprises already possess the data required for AI initiatives. The challenge emerges when organizations attempt to assemble a reliable, consistent representation of that data across systems, business domains, and operational contexts.
Customer data provides one of the clearest examples. Identity, transaction history, support interactions, loyalty activity, pricing eligibility, and product usage often exist across:
- CRM platforms
- e-commerce systems
- ERP environments
- customer support tools
- marketing automation platforms
- and external partner systems
Although these systems may technically exchange data, they frequently operate with:
- different identifiers
- different update cycles
- different definitions
- and different assumptions about what constitutes a customer, transaction, or interaction
Under traditional reporting models, analysts often compensate for these inconsistencies manually. In AI environments, those contradictions become embedded directly into training datasets, recommendation pipelines, retrieval systems, and inference logic.
In practice, these inconsistencies surface across multiple types of AI systems, for example:
- A recommendation engine trained on inconsistent customer histories may generate inaccurate personalization patterns.
- A copilot retrieving product information from disconnected systems may combine outdated specifications with current pricing logic.
- Forecasting systems may consume conflicting operational metrics originating from separate business domains.
These environments create a dangerous illusion of readiness: the data exists, the integrations exist, and the pipelines exist — yet the organization still lacks a reliable operational representation of reality that AI systems can consume consistently.
Data quality issues remain invisible until AI consumes them directly
Many organizations believe their data quality is sufficient because operational reporting still functions adequately. Dashboards load correctly, KPIs appear stable, and business teams continue making decisions using existing reports.
This perception often masks extensive manual stabilization happening behind the scenes.
In practice:
- analysts correct records before reporting
- operational teams compensate for missing values
- inconsistent attributes are patched locally
- and business users learn which fields can or cannot be trusted
Traditional analytics workflows allowed these issues to remain partially hidden because humans continuously interpreted and corrected the data before acting on it.
AI systems remove much of that human correction layer.
When AI models consume enterprise data directly:
- inconsistent labels propagate into training sets
- duplicate entities distort recommendations
- outdated records influence generated responses
- and incomplete metadata weakens retrieval accuracy
Many organizations encounter these problems only after deployment, particularly in:
- retrieval-augmented generation (RAG) environments
- document intelligence systems
- AI copilots
- recommendation engines
- and predictive analytics platforms
At that stage, organizations often discover that their historical definition of “acceptable data quality” was heavily dependent on human intervention that no longer exists inside AI-driven workflows.
Enterprise data was never designed for AI consumption
Most enterprise data environments were originally built to support transactions, reporting, compliance, and operational processes. AI introduces a fundamentally different consumption model.
Traditional systems primarily stored and transferred data between applications and human users. AI systems continuously interpret, combine, rank, summarize, classify, and generate outputs from that data.
This distinction changes the requirements significantly.
In many organizations, data pipelines still reflect the structure of source systems rather than the logic of AI use cases. As a result:
- critical contextual attributes are missing
- relationships between entities remain unclear
- metadata is incomplete
- and business meaning exists primarily inside human interpretation
These limitations become particularly visible in AI workflows requiring semantic consistency.
For example:
- recommendation systems require stable behavioral context
- copilots require traceable source attribution
- forecasting models require standardized historical signals
- and retrieval systems require structured contextual metadata to rank information correctly
Datasets may remain technically valid while still failing operationally inside AI systems because the surrounding context required for interpretation was never modeled explicitly.
Organizations frequently attempt to solve this problem by expanding data collection efforts. In practice, excessive data volume often amplifies the problem further:
- irrelevant attributes increase noise
- weak metadata reduces retrieval precision
- and unclear semantic relationships introduce ambiguity into model outputs
AI systems perform best in environments where data carries explicit meaning, ownership, lineage, and contextual structure — not simply large-scale storage capacity.
Unstructured data exposes the largest readiness gap
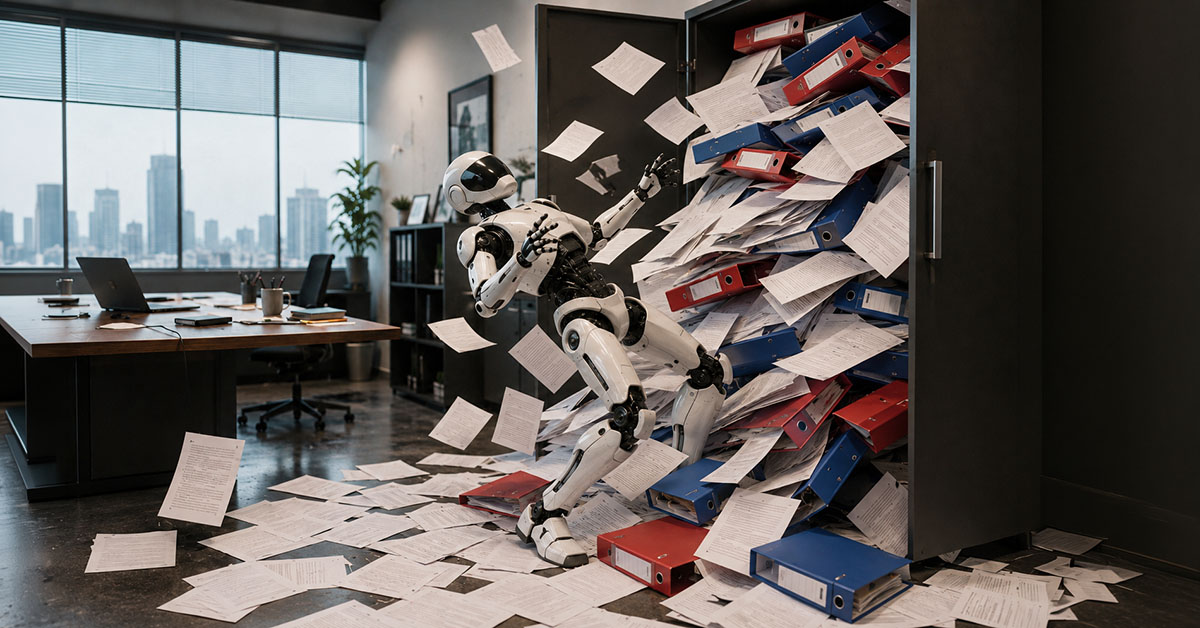
For many organizations, the most valuable information relevant to AI initiatives does not exist inside structured databases.
It exists inside:
- technical documentation
- contracts
- service records
- product specifications
- engineering notes
- support conversations
- emails
- PDFs
- knowledge bases
- and operational documentation accumulated over years
This data often contains the context AI systems need most: product behavior, operational procedures, customer intent, historical decisions, technical constraints, and institutional knowledge.
Despite its value, unstructured enterprise content remains largely unmanaged in many organizations.
Common conditions include:
- inconsistent classification
- fragmented ownership
- missing metadata
- outdated versions of documents
- duplicated content
- and unclear access governance
These limitations become immediately visible in enterprise copilots and retrieval-augmented AI applications, where poorly governed repositories frequently produce:
- contradictory responses
- outdated recommendations
- incomplete summaries
- or answers derived from low-authority documents
In many deployments, organizations initially interpret these failures as “hallucinations.” Closer analysis often reveals that the model retrieved low-quality, duplicated, outdated, or contextually incomplete enterprise content.
Retrieval quality, source traceability, document hierarchy, metadata consistency, and content governance increasingly determine the reliability of enterprise AI systems.
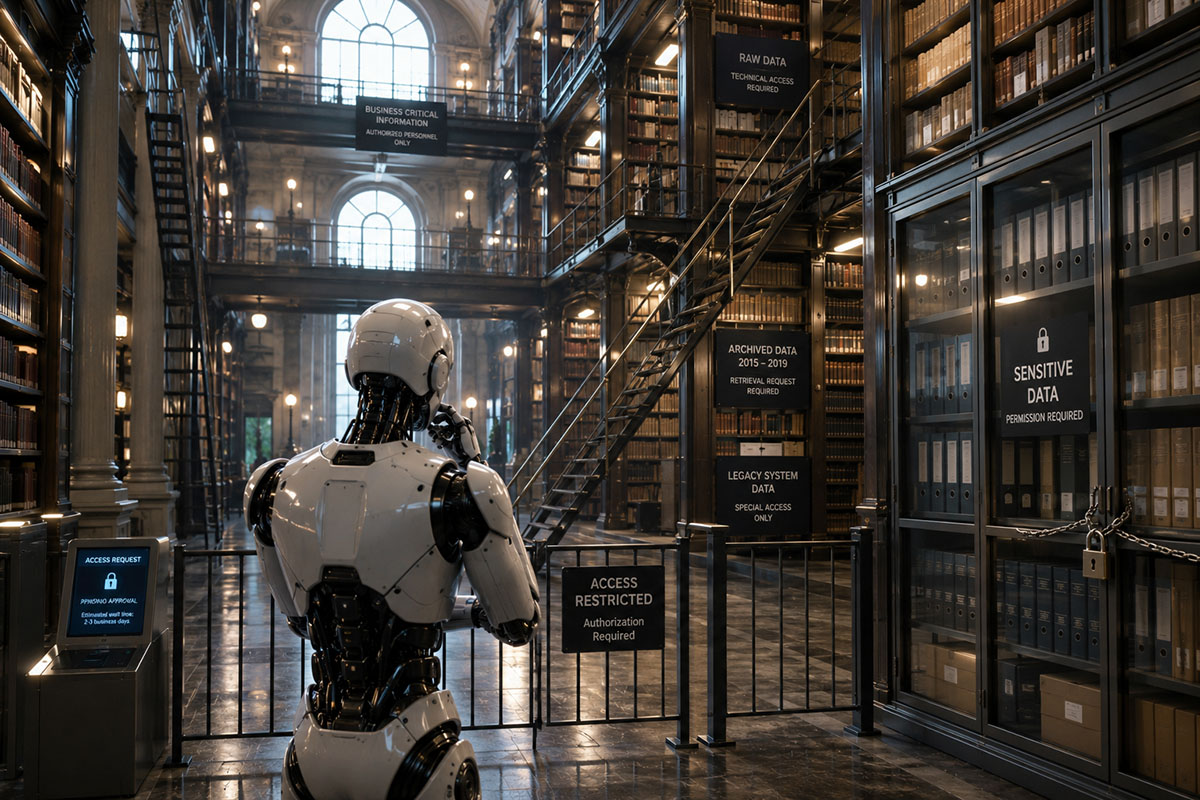
Data access still depends on operational friction
Many enterprises describe their data as accessible because it technically exists within centralized platforms or integrated environments.
Operational reality often looks very different.
Access to relevant datasets may still require:
- approval chains
- manual extraction
- ticket-based processes
- local transformations
- or direct support from engineering teams
Documentation frequently remains incomplete or outdated, particularly around:
- lineage
- business definitions
- transformation logic
- and historical changes
As AI adoption expands across departments, these access limitations begin creating significant operational bottlenecks.
Teams respond predictably:
- local copies of datasets proliferate
- shadow pipelines emerge
- business units create independent retrieval logic
- and isolated AI experiments evolve outside centralized governance structures
Over time, organizations accumulate multiple competing versions of the same operational reality — each feeding separate AI workflows with slightly different assumptions, transformation rules, and semantic interpretations.
Under these conditions, reproducibility deteriorates rapidly.
The same prompt, model, or retrieval query may produce different outputs depending on which version of enterprise data an AI system accesses internally.
Ownership remains unclear across the data lifecycle
Many organizations still manage data primarily through the lens of systems and applications rather than reusable operational assets.
Ownership therefore becomes fragmented:
- application teams manage systems
- platform teams manage infrastructure
- analytics teams manage reporting
- governance teams define policies
- while accountability for long-term data usability often remains undefined
This fragmentation creates persistent operational problems for AI initiatives:
- Definitions drift across departments.
- Local fixes accumulate without upstream correction.
- Transformation logic becomes embedded inside isolated workflows.
- Knowledge about data meaning remains concentrated within specific teams or individuals.
AI systems magnify these weaknesses because they depend on stable semantics and repeatable interpretation across environments.
Without clear ownership:
- metadata deteriorates
- lineage becomes unreliable
- retrieval quality declines
- and AI outputs become increasingly difficult to validate or explain
Organizations frequently discover these governance gaps only after scaling AI initiatives across multiple domains and business units.
By that point, operational complexity has often increased significantly.
Conclusion
Many organizations currently evaluating their AI maturity are actually evaluating infrastructure maturity, analytics maturity, or platform maturity rather than data readiness for AI itself.
AI systems introduce a fundamentally different operating model for enterprise data:
- direct machine consumption
- continuous large-scale interpretation
- automated retrieval
- semantic dependency
- and reduced tolerance for ambiguity or inconsistency
Under these conditions, long-standing enterprise data limitations become highly visible.
Fragmented definitions, unstable quality, unmanaged unstructured content, operational access barriers, and weak ownership models directly influence the reliability of AI outputs.
Organizations that successfully operationalize AI at scale typically treat data differently:
not simply as stored information, but as a continuously governed operational asset designed for machine consumption, semantic consistency, traceability, and automated use.
The next step is understanding what such an environment actually looks like in practice.
That is what we will address in Part 2.
You might also like:
- AI in E-Commerce (E-Book) » Learn more
- What Google’s Universal Commerce Protocol Signals for the Future of B2B Commerce » Learn more
- Agentic Commerce: Where Conversations Become Transactions » Learn more
- Agentic Commerce: Winners, Losers, and the Forces Behind the Change » Learn more
- Agentic Commerce: Strategic Priorities for Executive Leaders » Learn more
- Generative AI unlocks the value of unstructured data in insurance » Learn more